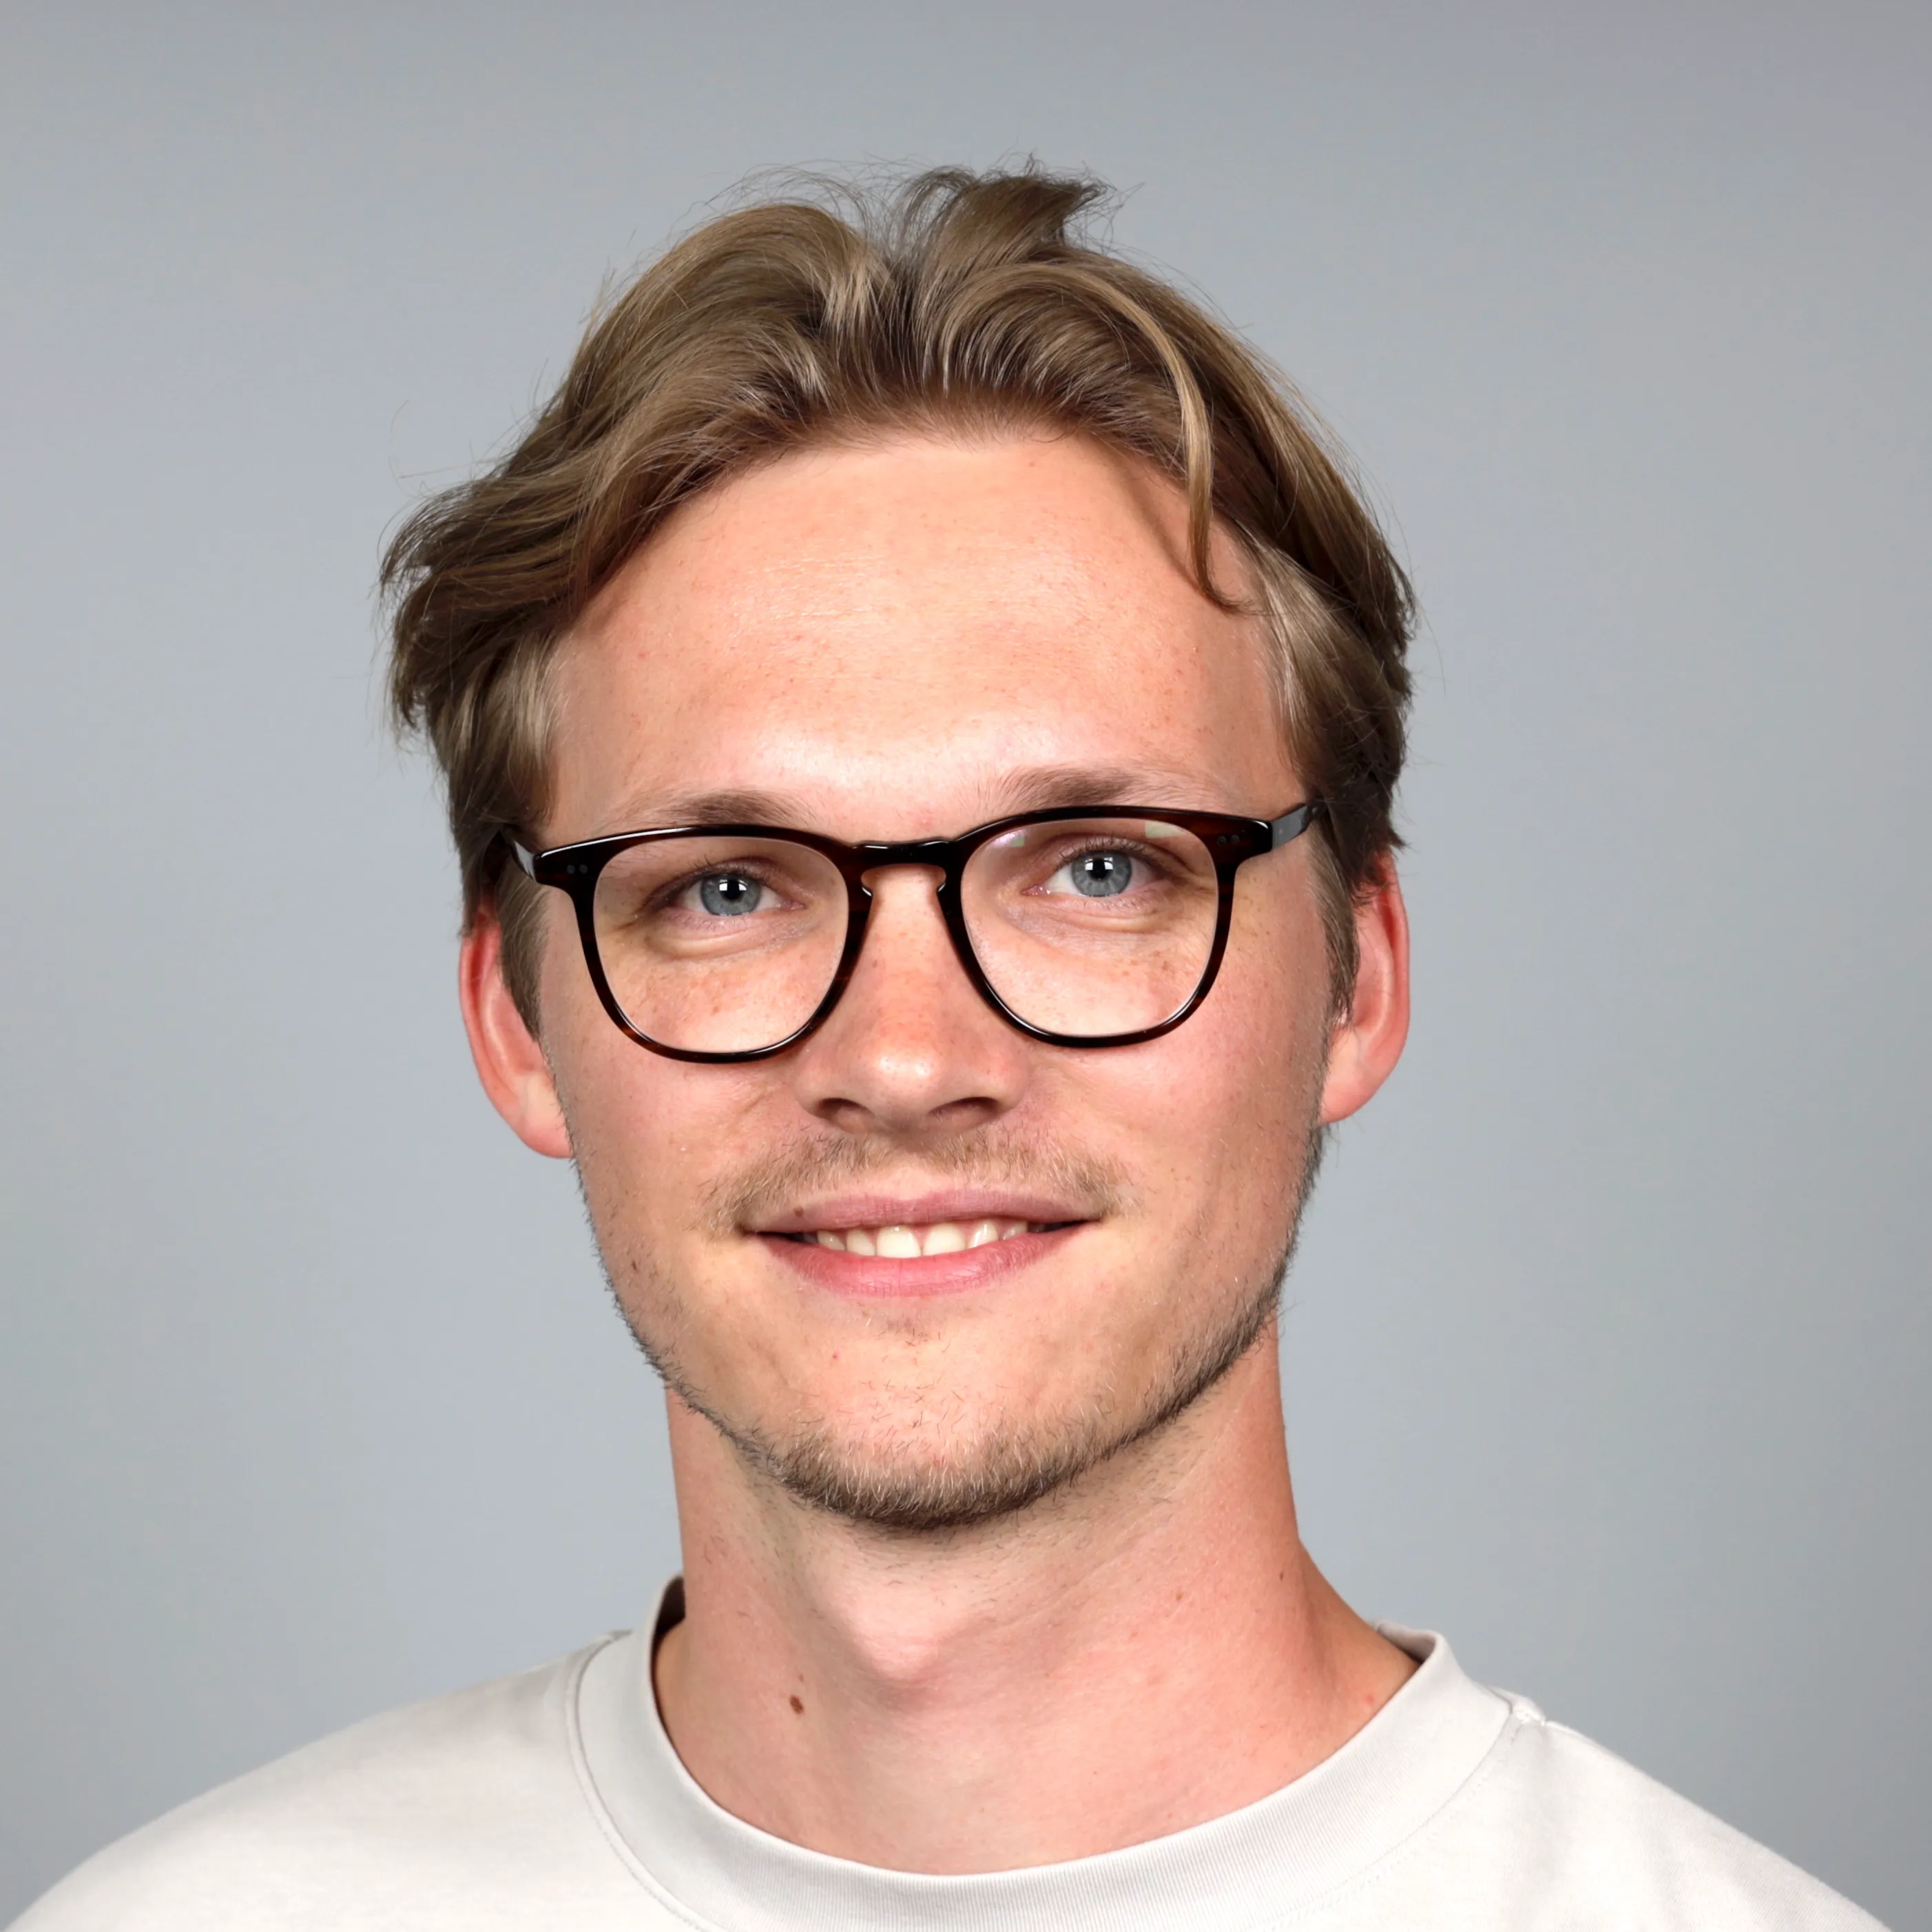
Maximilian Dreyer
Interpretability for safe and reliable AI
- Co-founder, layerwise
- Postdoctoral Researcher, Fraunhofer HHI
- Berlin
I build methods that look inside AI models. They reveal which concepts a model has learned and relies on, uncover hidden flaws such as shortcuts and biases, and fix them directly inside the model. With layerwise, I bring this into practice by monitoring and steering AI systems while they run.
Co-founder · with Reduan Achtibat and Oleg Hein
Interpretability, in production.
layerwise is a Fraunhofer HHI spin-off building interpretable AI tooling for teams that need to understand model behaviour before it reaches real-world decisions. Instead of judging outputs after the fact, we read and steer a model’s internal signals at inference time to detect and correct failures such as hallucination, manipulation and prompt injection in language models and agents.
news
- Sep 2026New preprint: ResLRP shows why attributions in Vision Transformers explode and how to fix it.
- Sep 2026Invited talk at Amazon Berlin: Right answer, wrong reason? From pixel-level grounding to concept-level auditing of VLMs.
- Jul 2026Talk on SemanticLens at the Interpretable Deep Learning Seminar Series.
- Jun 2026Tutorial From concepts to control at XAI4CV and invited talk at the Machine Unlearning for Vision workshop, both at CVPR 2026.
- 2026Co-founded layerwise to bring interpretability into production AI systems.
- Mar 2026Defended my PhD at TU Berlin, summa cum laude 🎉
- Nov 2025Keynote Inspecting AI like engineers at the Human-Centric AI Workshop, CIKM 2025.
- Aug 2025SemanticLens published in Nature Machine Intelligence.
- Apr 2025Keynote on mechanistic concept discovery at the ICLR 2025 XAI4Science Workshop.
research
AI models are trained, not engineered, so nobody specifies what their inner parts do. My research makes them understandable, checkable and fixable.
- 1.UnderstandConcept Relevance Propagation
Understanding decisions through the concepts a model uses.
89% vs. 54%
of users spotted a flawed model with our explanations, vs. standard heatmaps
- 2.AuditSemanticLens & PCX
Searching a model’s inner parts by text and checking what it has learned against expert knowledge.
0 of 27
image classes in a widely used model relied only on valid features
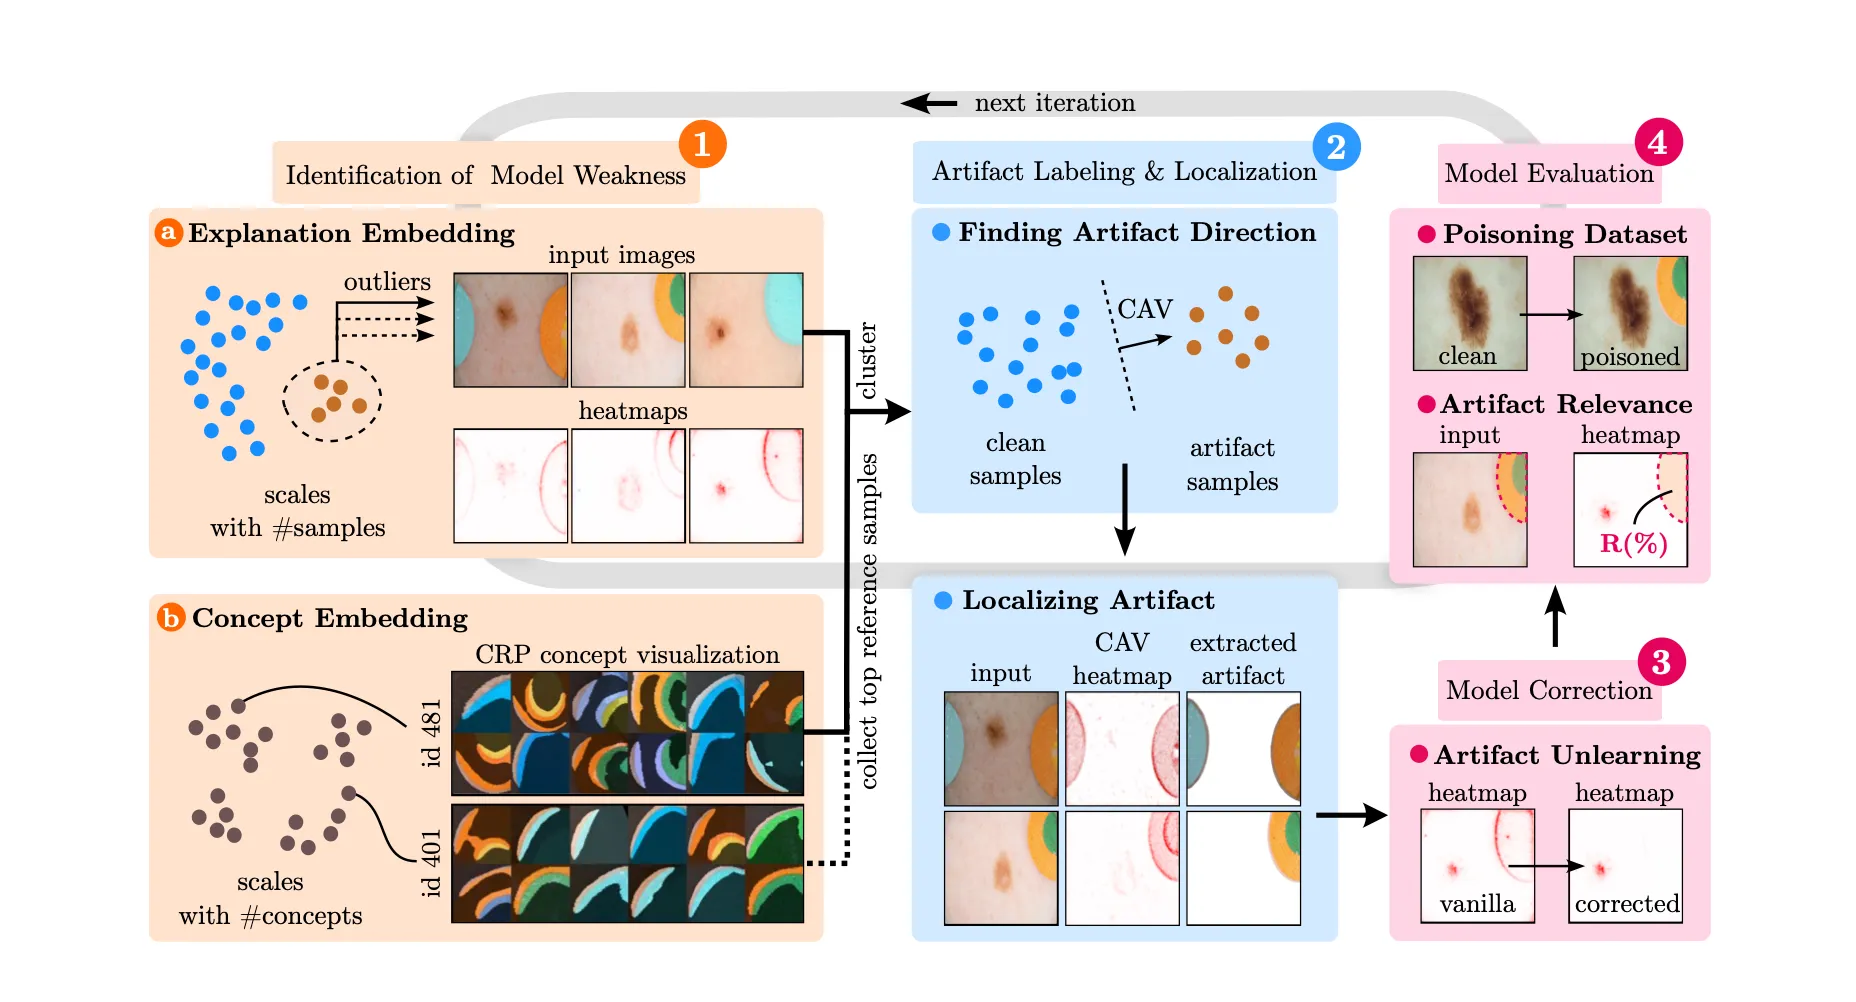
- 3.CorrectRR-ClArC & Reveal2Revise
Removing unwanted behaviour inside the model and checking the fix, without needing human annotations.
up to +28%
accuracy on biased test data after correction
work
Selected publications
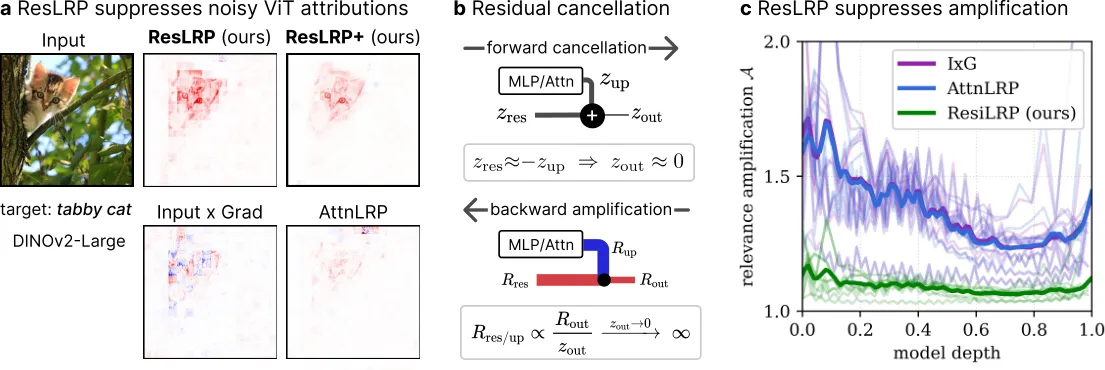 Preprint 2026Senior author
ResLRP: The Role of Residual Cancellation in Attribution Instability in Vision Transformers
Cancellations in residual pathways cause attributions in ViTs to explode. Treating residual connections correctly yields fine-grained, faithful and stable explanations.
Jim Berend, Reduan Achtibat, Daniel Schäffer, Alexander Binder, Wojciech Samek, Sebastian Lapuschkin, Maximilian Dreyer
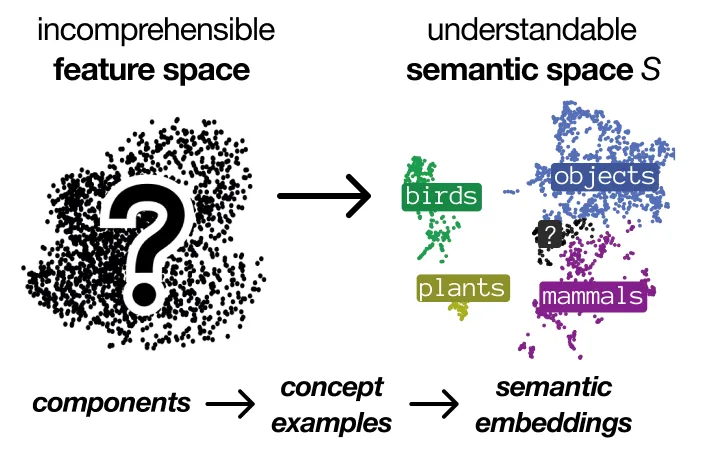 Nature Machine Intelligence 2025
Mechanistic understanding and validation of large AI models with SemanticLens
A search engine for the inside of AI models: every component is mapped into a shared space of images and language, so a model can be searched, described, compared and audited.
Maximilian Dreyer*, Jim Berend*, Tobias Labarta, Johanna Vielhaben, Thomas Wiegand, Sebastian Lapuschkin, Wojciech Samek
 ICLR 2026
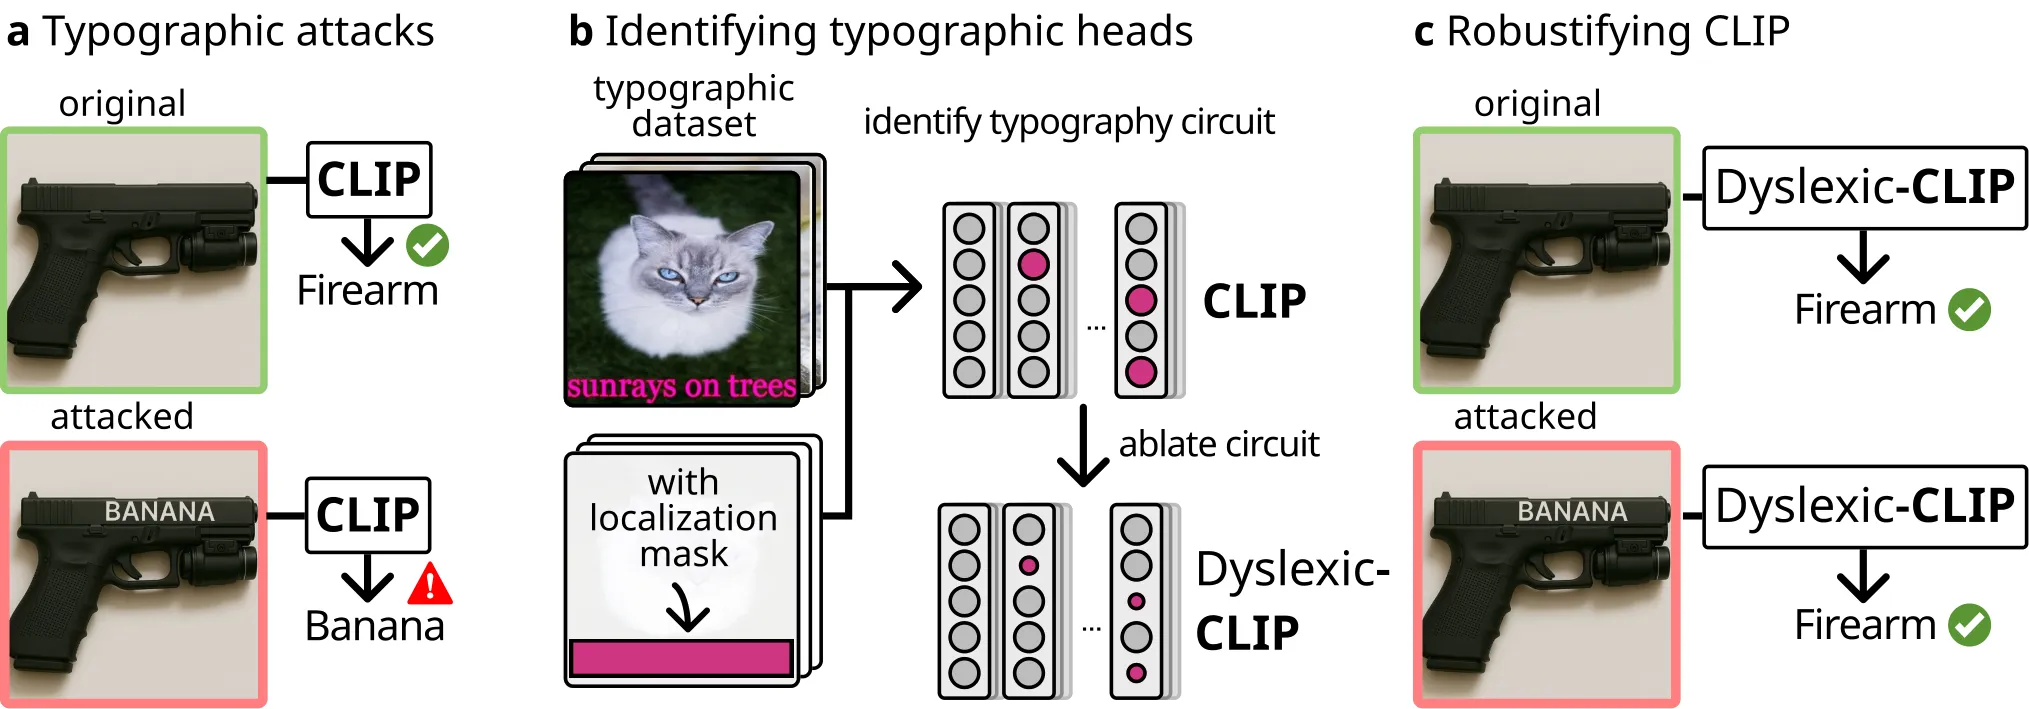
Dyslexify: A mechanistic defense against typographic attacks in CLIP
Locates the attention-head circuit that reads text in images and ablates it, making CLIP robust to typographic attacks.
Lorenz Hufe, Constantin Venhoff, Maximilian Dreyer, Erblina Purelku, Sebastian Lapuschkin, Wojciech Samek
 Preprint 2025
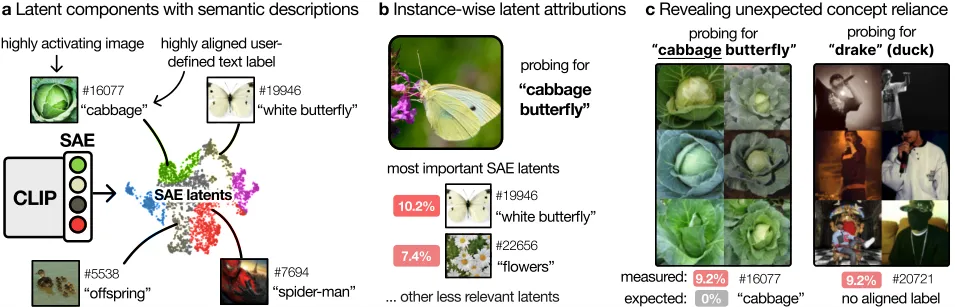
From What to How: Attributing CLIP’s latent components reveals unexpected semantic reliance
Combines sparse autoencoders with attribution patching to reveal not only what CLIP’s components encode, but how they drive its predictions.
Maximilian Dreyer, Lorenz Hufe, Jim Berend, Thomas Wiegand, Sebastian Lapuschkin, Wojciech Samek
 ICML 2024
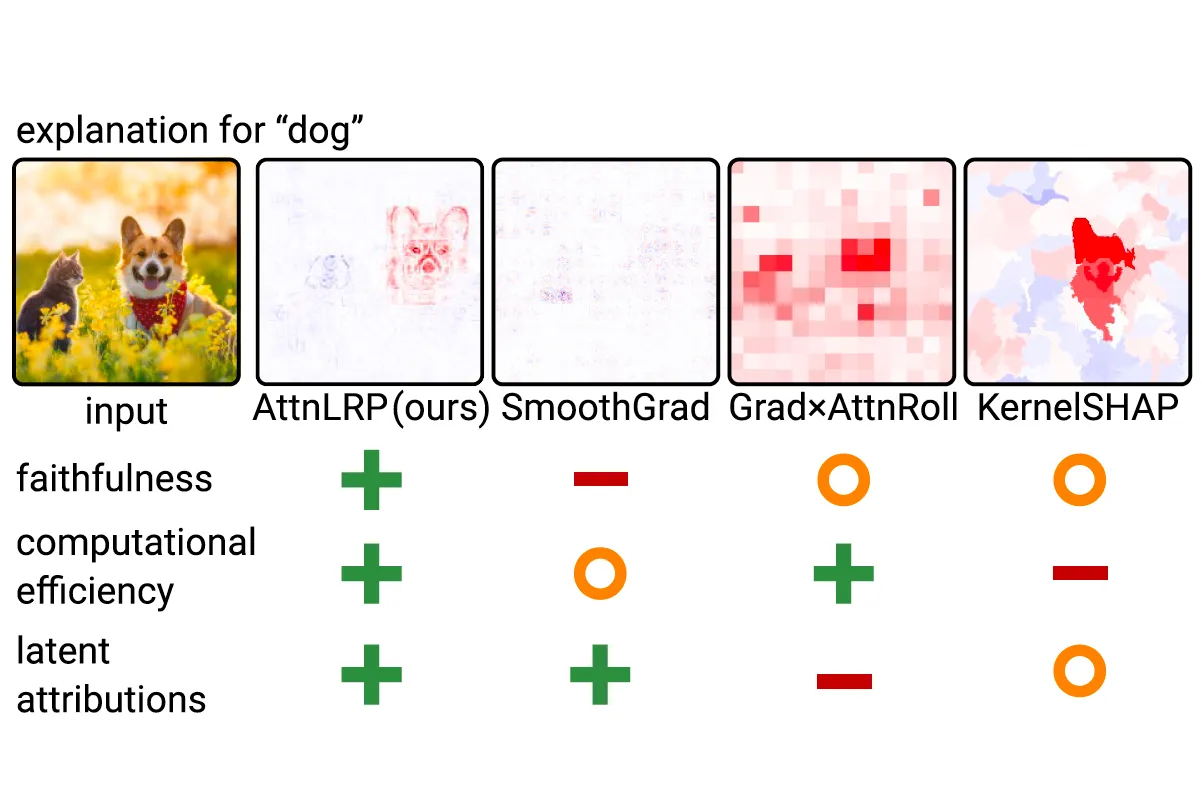
AttnLRP: Attention-aware layer-wise relevance propagation for transformers
Extends LRP to attention layers, enabling faithful and efficient explanations of LLMs and Vision Transformers.
Reduan Achtibat, Sayed M. V. Hatefi, Maximilian Dreyer, Aakriti Jain, Thomas Wiegand, Sebastian Lapuschkin, Wojciech Samek
 Nature Machine Intelligence 2023
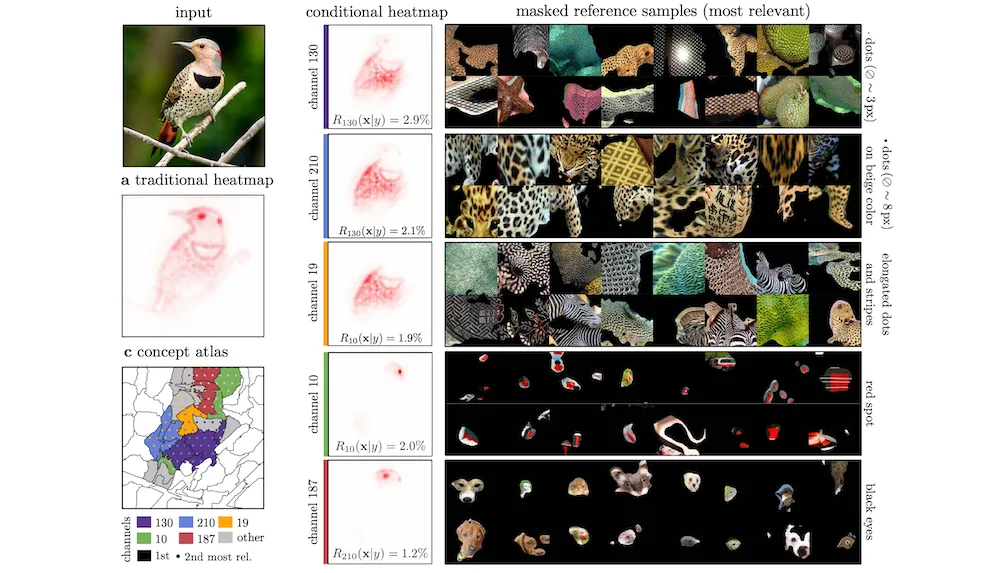
From attribution maps to human-understandable explanations through Concept Relevance Propagation
Explains not only where a model looks, but what it sees there, by attributing decisions to the concepts encoded in its hidden units.
Reduan Achtibat*, Maximilian Dreyer*, Ilona Eisenbraun, Sebastian Bosse, Thomas Wiegand, Wojciech Samek, Sebastian Lapuschkin
 AAAI 2024
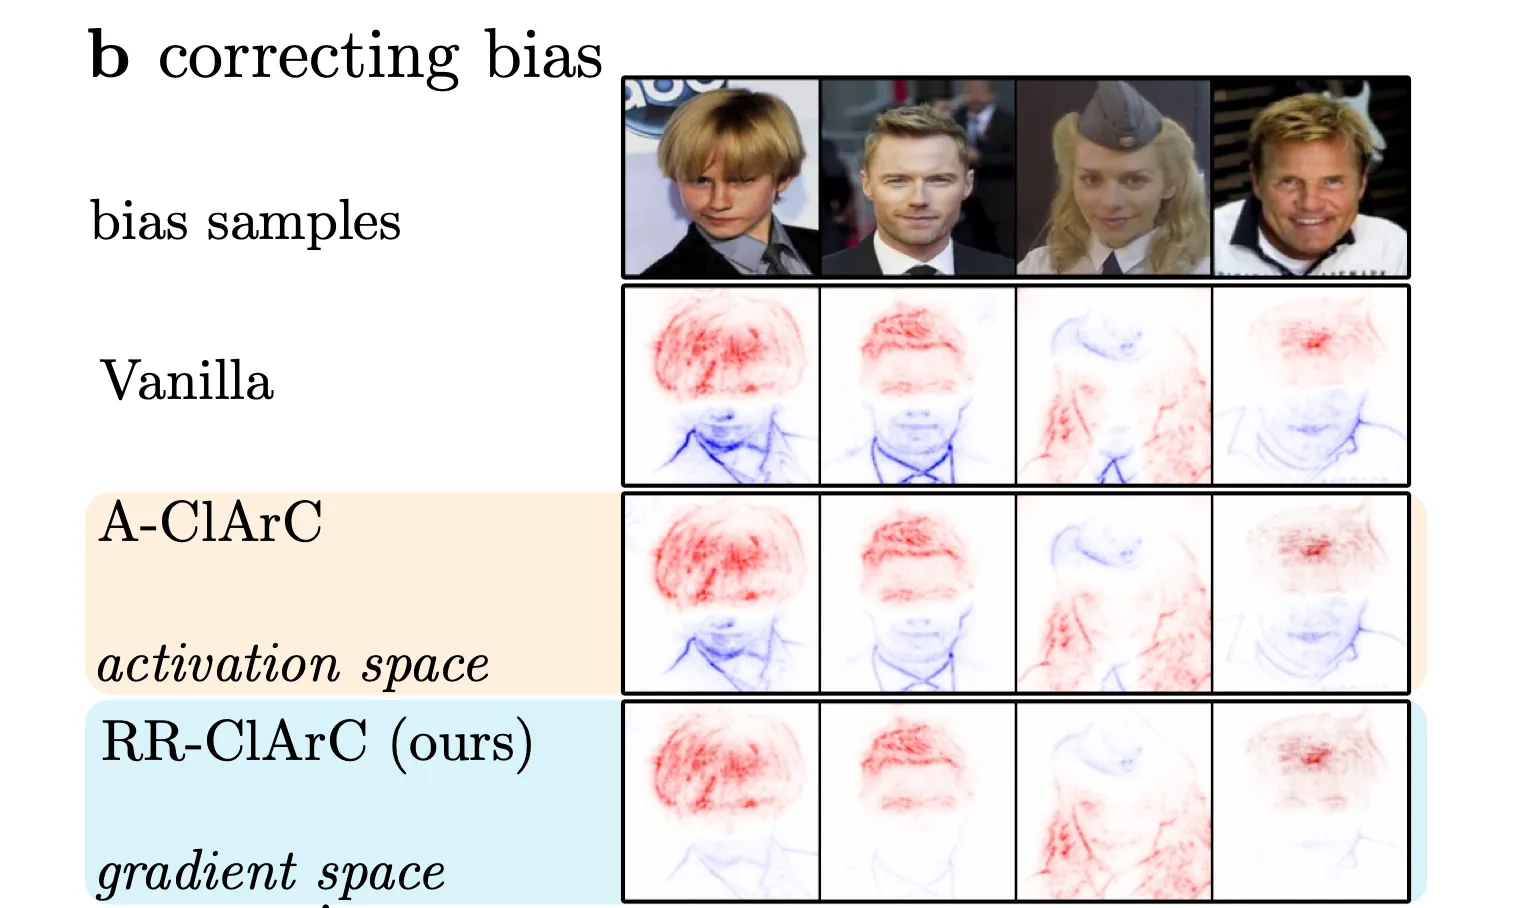
From hope to safety: Unlearning biases of deep models via gradient penalization in latent space
RR-ClArC unlearns spurious concepts by penalizing the model’s sensitivity to them in latent space.
Maximilian Dreyer*, Frederik Pahde*, Christopher J. Anders, Wojciech Samek, Sebastian Lapuschkin
 CVPR Workshops 2024
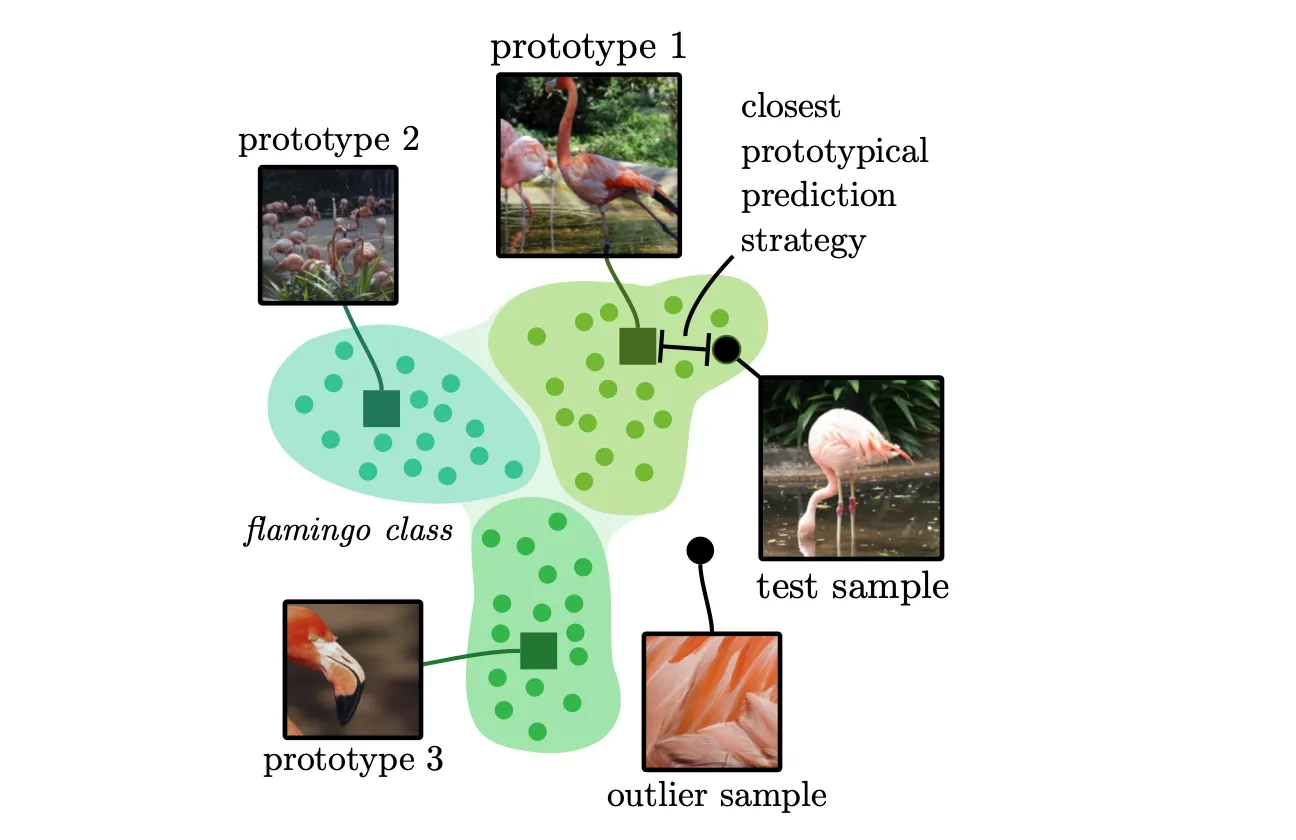
Understanding the (extra-)ordinary: Validating deep model decisions with prototypical concept-based explanations
Concept-based prototypes summarize a model’s strategies, so unusual behaviour and data-quality issues stand out automatically.
Maximilian Dreyer, Reduan Achtibat, Wojciech Samek, Sebastian Lapuschkin
 CVPR Workshops 2024Spotlight
PURE: Turning polysemantic neurons into pure features by identifying relevant circuits
Disentangles polysemantic units into monosemantic features via their circuits, increasing latent interpretability.
Maximilian Dreyer, Erblina Purelku, Johanna Vielhaben, Wojciech Samek, Sebastian Lapuschkin
More publications
Contrastive Semantic Projection: Faithful neuron labeling with contrastive examples
Oussama Bouanani, Jim Berend, Wojciech Samek, Sebastian Lapuschkin, Maximilian Dreyer
World Conference on XAI 2026 · Senior author
From attribution to action: A human-centered application of activation steering
Tobias Labarta, Maximilian Dreyer, Katharina Weitz, Wojciech Samek, Sebastian Lapuschkin
CVPR Workshops 2026
Navigating neural space: Revisiting concept activation vectors to overcome directional divergence
Frederik Pahde, Maximilian Dreyer, Moritz Weckbecker, Leander Weber, Christopher J. Anders, Thomas Wiegand, Wojciech Samek, Sebastian Lapuschkin
ICLR 2025
Attribution-guided pruning for insight and control: Circuit discovery and targeted correction in small-scale LLMs
Sayed M. V. Hatefi, Maximilian Dreyer, Reduan Achtibat, Patrick Kahardipraja, Thomas Wiegand, Wojciech Samek, Alexander Binder, Sebastian Lapuschkin
Preprint 2025
Pruning by explaining revisited: Optimizing attribution methods to prune CNNs and transformers
Sayed M. V. Hatefi, Maximilian Dreyer, Reduan Achtibat, Thomas Wiegand, Wojciech Samek, Sebastian Lapuschkin
ECCV Workshops 2024
Reactive model correction: Mitigating harm to task-relevant features via conditional bias suppression
Dilyara Bareeva, Maximilian Dreyer, Frederik Pahde, Wojciech Samek, Sebastian Lapuschkin
CVPR Workshops 2024
Explainable concept mappings of MRI: Revealing the mechanisms underlying deep learning-based brain disease classification
Christian Tinauer, Anna Damulina, Maximilian Sackl, Martin Soellradl, Reduan Achtibat, Maximilian Dreyer, Frederik Pahde, Sebastian Lapuschkin, et al.
World Conference on XAI 2024
Revealing hidden context bias in segmentation and object detection through concept-specific explanations
Maximilian Dreyer, Reduan Achtibat, Thomas Wiegand, Wojciech Samek, Sebastian Lapuschkin
CVPR Workshops 2023
Explainability-driven quantization for low-bit and sparse DNNs
Daniel Becking, Maximilian Dreyer, Wojciech Samek, Karsten Müller, Sebastian Lapuschkin
xxAI – Beyond Explainable AI 2022
* equal contribution. Full list on Google Scholar.
talks
- Sep 2026
Right answer, wrong reason? From pixel-level grounding to concept-level auditing of VLMs
Amazon, Berlin
- Jul 2026
Mechanistic understanding and validation of large AI models with SemanticLens
- Jun 2026
From concepts to control: Diagnosing and steering vision foundation models
Tutorial, XAI4CV, CVPR 2026
- Jun 2026
From explanation to unlearning: Concept-based diagnosis and control
- Nov 2025
Inspecting AI like engineers: From explanation to validation with SemanticLens
- Apr 2025
Probing for the unknown: Mechanistic concept discovery beyond human expectation
- Jan 2025
SemanticLens: A search engine to find bugs in large AI models
Fraunhofer AI Days
- Nov 2024
Concept-based monitoring and debugging of model behavior
- Oct 2024
Pruning vision transformers using layer-wise relevance propagation
- May 2024
From attribution maps to human-understandable explanations with CRP
- Feb 2024
Debugging biases of deep medical models
Stanford MedAIvideo
cv
Positions
since 2026
Co-founder
layerwise
Fraunhofer HHI spin-off reading and steering a model’s internal signals to detect and correct failures such as hallucinations and prompt injection.
since 2026
Postdoctoral Researcher
Fraunhofer HHI
Explainable AI Group (Dr. S. Lapuschkin), Department of Artificial Intelligence (Prof. W. Samek).
2022 – 2026
Doctoral Researcher
Fraunhofer HHI
Concept-based explanations, model auditing and bias correction; medical imaging applications.
2020 – 2022
Student Research Assistant
Fraunhofer HHI
XAI for segmentation and object detection, explainability-driven quantization.
2016 – 2020
Student positions
IAV Berlin, Baumer Hübner, DESY Zeuthen
Autonomous-driving simulation, sensor metrology, teaching.
Education
2026
Dr. rer. nat., summa cum laude
Technische Universität Berlin
2022
M.Sc. Computational Science
University of Potsdam
Thesis on concept-based explanations for segmentation and object detection, awarded by the Friends of Fraunhofer HHI.
2019
B.Sc. Physics
Humboldt-Universität zu Berlin
Exchange semester at Uppsala University, 2018.
- Patents
- Inventor on three Fraunhofer patent families: SemanticLens (lead inventor), Concept Relevance Propagation and AttnLRP.
- Software
- Open-source implementations of all methods, including zennit-crp, LXT (LRP for transformers) and semanticlens, with about 530 GitHub stars.
- Mentoring
- Supervised nine Master’s and doctoral students, including as senior author on their work.
- Award
- Young Talent Award of the Friends of Fraunhofer HHI for the Master’s thesis, 2022.
contact
I live in Berlin and work on making AI systems understandable, monitorable and correctable, in research at Fraunhofer HHI and in practice with layerwise. I’m always happy to talk about interpretability, AI safety or collaborations.